My work explores the development of AI systems through their convergence with practices of media and arts, in regard to the inherited philosophical, ethical, and aesthetical implications.
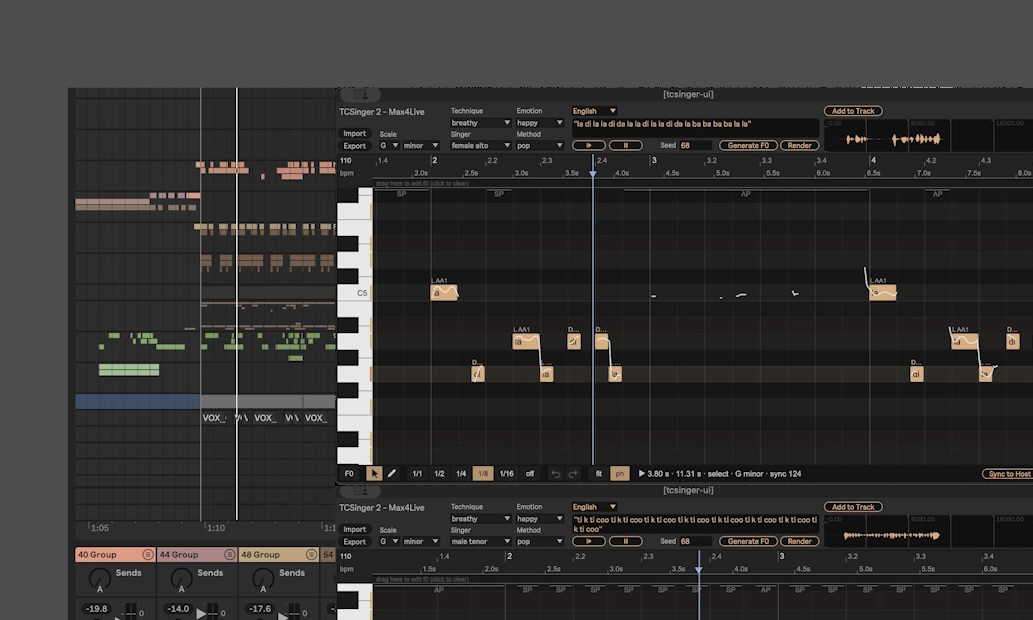
TCSinger2: Singing Voice Synthesis in Max/MSP
Modern Singing Voice Synthesis (SVS) systems use neural audio synthesis, where generative models learn from large collections of recordings to capture the qualities that make a voice sound human...
Category Research Subject Neural Audio Synthesis Date Oct, 2026

Latent Terrain: Dissecting Neural Audio Codecs
Building new musical instruments that compose and interact with AI audio generators. Turning sound collections into a 2D terrain that you can perform.
Category Research Subject Creative AI Date Jun, 2026

Rubber Duck: LLM agents for learning creative coding
A customised agent for AI coding support, tailored for learners with the aim of reducing technical barriers to AI literacy and fair assessments. Reflection on how to actually embrace AI coding tools in UK higher education...
Category Research Subject Creative AI Date Jan, 2026
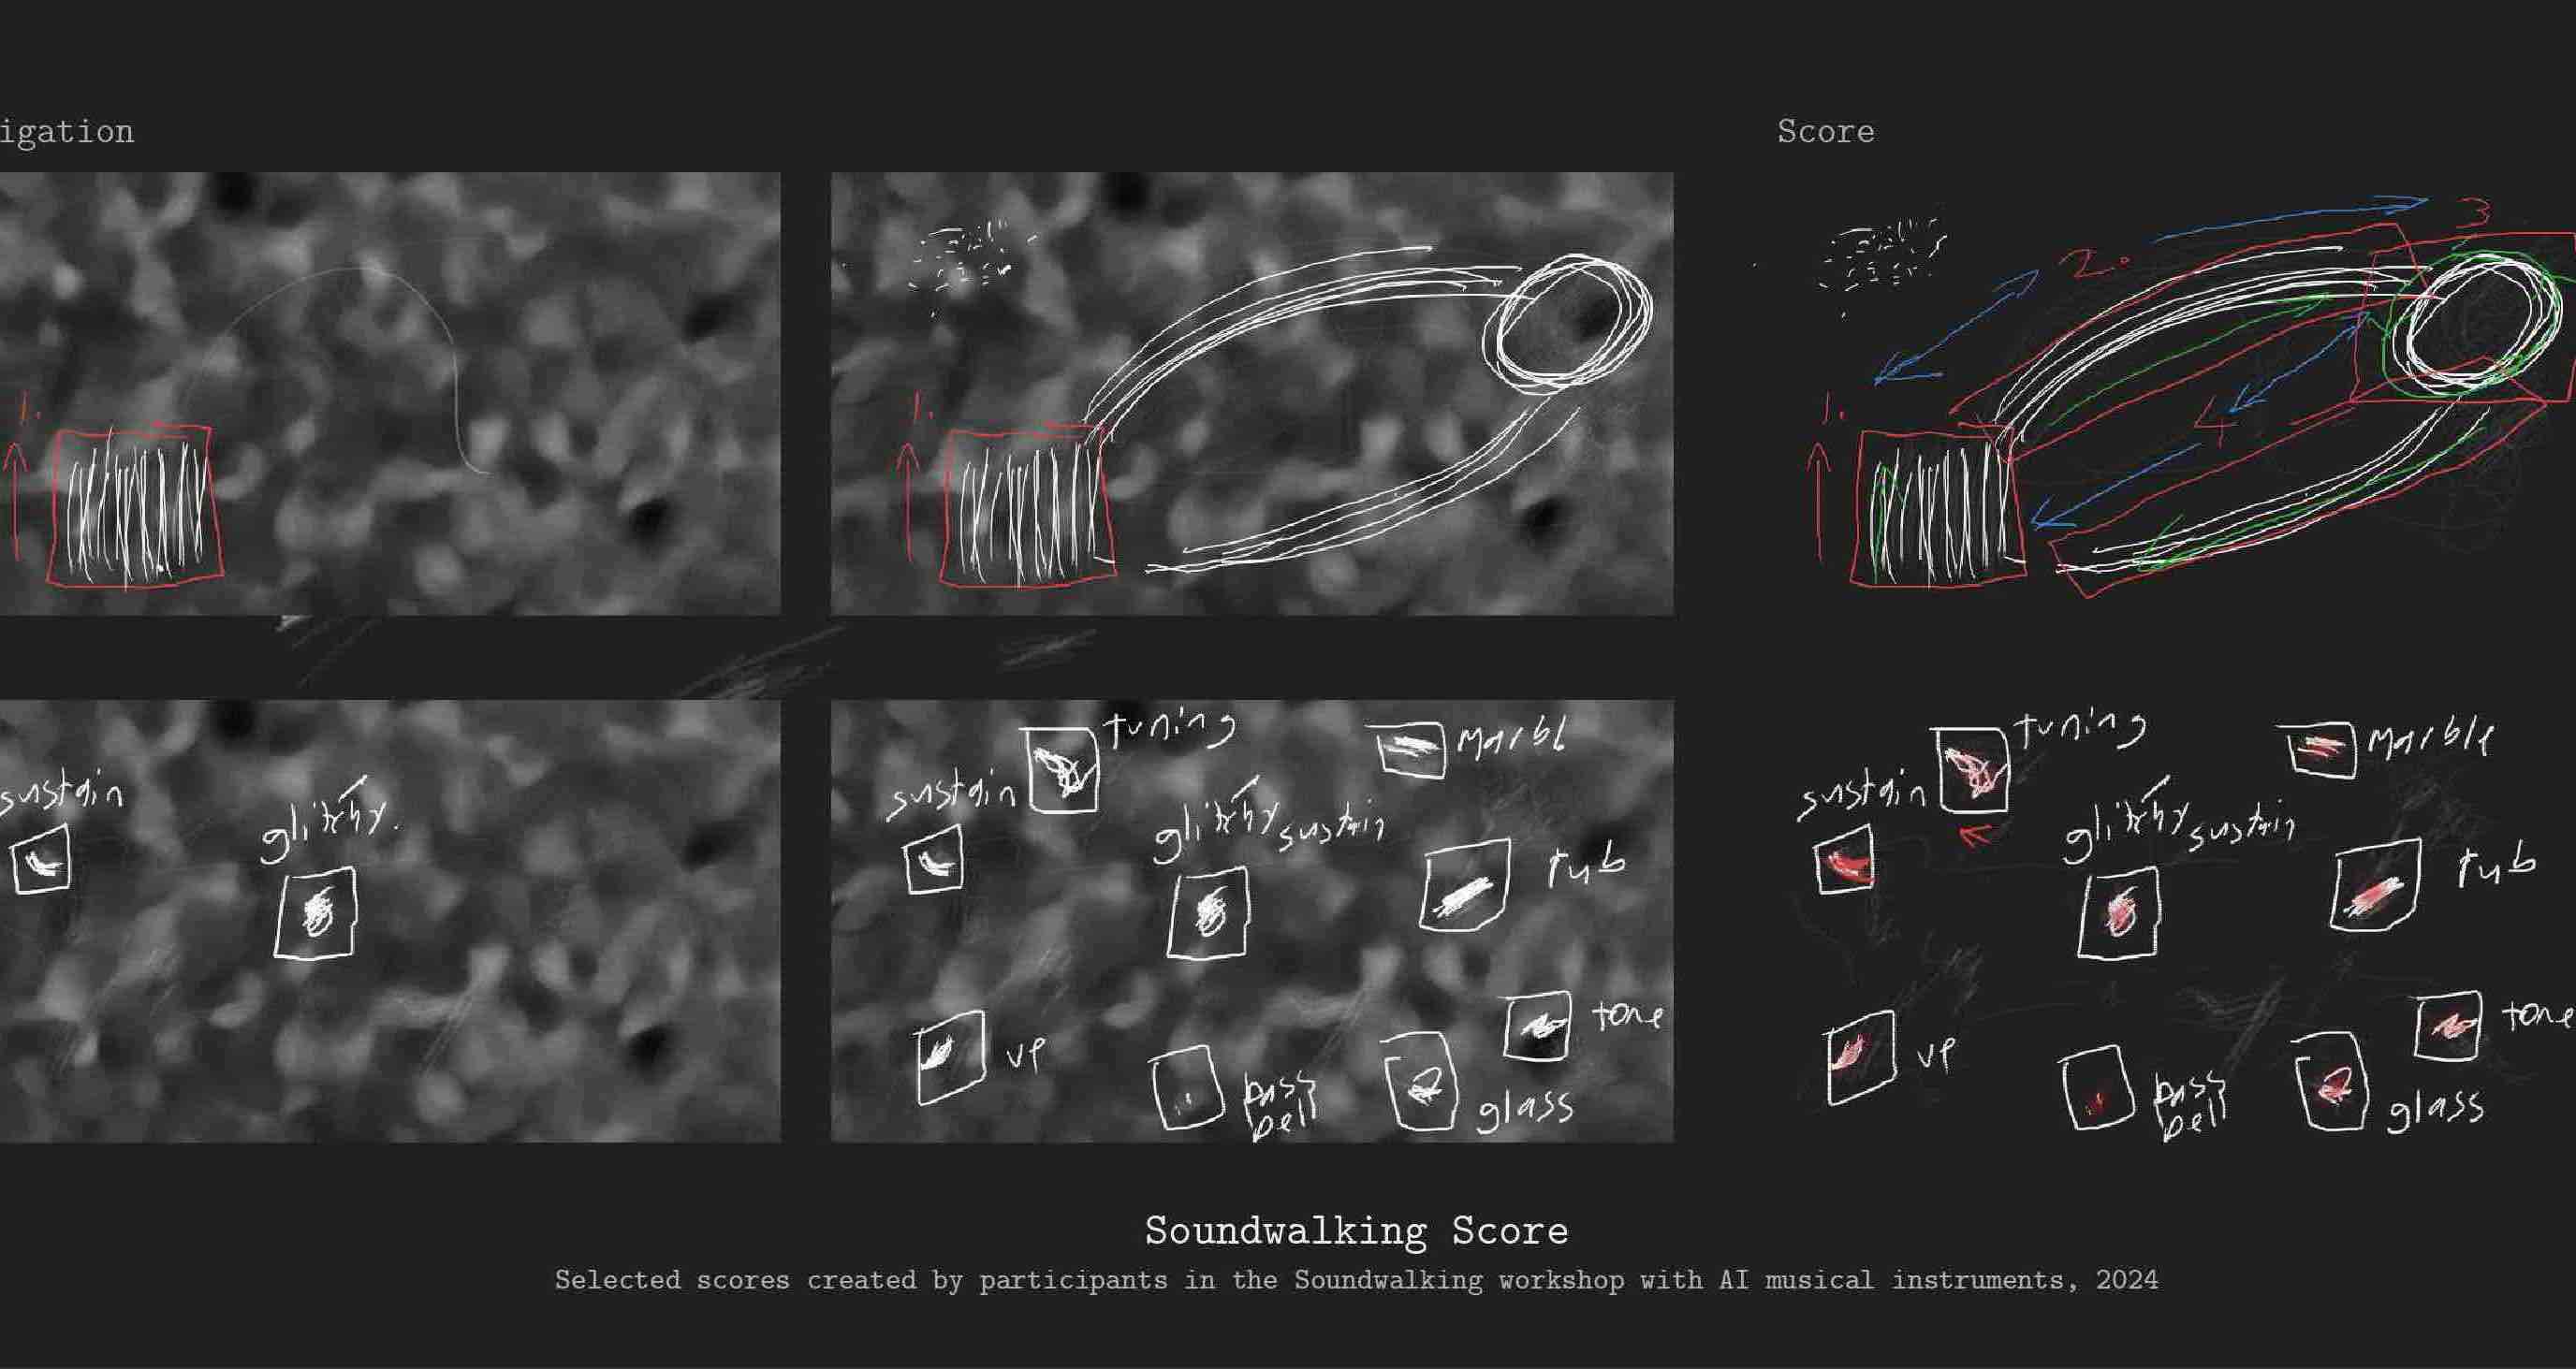
Embodied AI: Writing music in/with neural audio models
A study on how we (musicians) learn performing techniques, create musical notations, and use musical gestures in the computational representations of AI (neural audio) models.
Category Research Subject Creative AI Date Aug, 2025
Sketch-to-Sound Mapping with Interactive Machine Learning
Exploring interactive (personalised) constructions of mappings between visual sketches and musical controls. An prototype that leverage unsupervised feature learning to generate latent mapping using interactive machine learning.
Category Research Subject Creative AI Date Feb, 2024
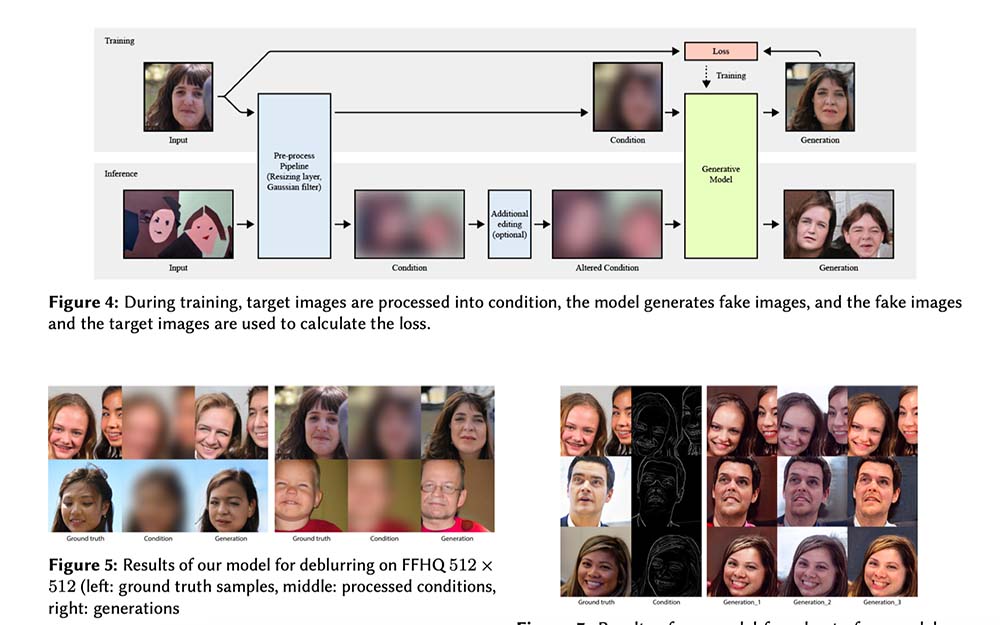
StyleGAN-Canvas: An augmented encoder for human-AI co-creation
We propose bridging the gap between StyleGAN3 and human-AI co-creative patterns by augmenting the latent variable model with the ability of image-conditional generation. The resulting model, StyleGAN-Canvas, solves various image-to-image translation tasks while maintaining the internal behaviour of StyleGAN3.
Category Research Subject Creative AI Date Mar, 2023